Dual Screening in Systematic Reviews: Conflicts and Kappa
Why systematic reviews use two independent screeners, what single screening misses, how to read Cohen's kappa, and how to resolve conflicts.
Dual screening means two people decide, independently, whether each record meets the review's eligibility criteria. Disagreements are resolved by discussion. When the disagreement is a difference in interpretation, another person can arbitrate. Cochrane Handbook section 4.6.4 describes that process and asks teams to define how disagreements will be resolved before screening starts. The same section calls duplicate title and abstract screening ideal, and it accepts a single screener for that first pass. Two independent people are essential for the full-text decision. The rest of this page is the title and abstract step: Include, Maybe, and Exclude, which pairs count as conflicts, how to read Cohen's kappa when nearly every record is an Exclude, and how one resolution queue finishes the work.
Why two screeners
Single screening of titles and abstracts misses studies that a second person would have kept.
Waffenschmidt and colleagues reviewed single versus double screening, published 28 June 2019 (BMC Medical Research Methodology). Four evaluations covered 23 single title-and-abstract screenings by nine reviewers. The median proportion of missed studies was 5% (range 0 to 58%): 3% for six experienced reviewers (range 0 to 21%) and 13% for three with less experience (range 0 to 58%). Their conclusion: single title and abstract screening is not equivalent to double screening, and an experienced reviewer might still use it as a shortcut in a rapid review.
Gartlehner and colleagues ran a crowd-based randomized trial on Cochrane Crowd (Journal of Clinical Epidemiology, 2020;121:20-28). After a training exercise, 280 participants made 24,942 decisions on 2,000 abstracts from two published reviews. Single-reviewer abstract screening missed 13% of relevant studies (sensitivity 86.6%, 95% CI 80.6% to 91.2%). Dual-reviewer screening missed 3% (sensitivity 97.5%, 95% CI 95.1% to 98.8%). Specificity was 79.2% with one reviewer and 68.7% with two, so the second person also keeps more abstracts that full text will drop. They concluded that single-reviewer abstract screening does not appear to meet the methodological standard they say decision makers expect of a systematic review, and that a rapid review may still use it.
Stoll and colleagues measured a second reviewer inside one large review, with highly experienced screeners and 15,000 search results in each approach (Research Synthesis Methods, 2019;10:539-545). With two reviewers throughout, the second person identified an additional 6.6% to 9.1% of eligible studies at title and abstract, and an additional 6.6% to 11.9% at full text. Joining only at full text added 4.4% to 5.3% of eligible studies. Those ranges are from one review.
Handbook section 4.6.4 cites Waffenschmidt 2019 and Gartlehner 2020, and it still allows one person to screen titles and abstracts. Waffenschmidt's medians were higher for less-experienced screeners. The protocol should record which approach you chose.
Polanin, Pigott, Espelage, and Grotpeter give management guidance for large abstract screens, which they describe as searches above about 1,000 citations (Research Synthesis Methods, 2019;10:330-342). In their example project, 14,923 citations were double-screened. They recommend double screening for training, accuracy, and reconciliation, and they recommend reconciling during screening, with a third person when a pair cannot agree. The paper does not estimate a miss rate for single screening.
Conflict vs Maybe
At title and abstract, two independent decisions use three labels: Include, Maybe, and Exclude. Maybe is a first-class state. It should flow into the same resolution queue as disagreements.
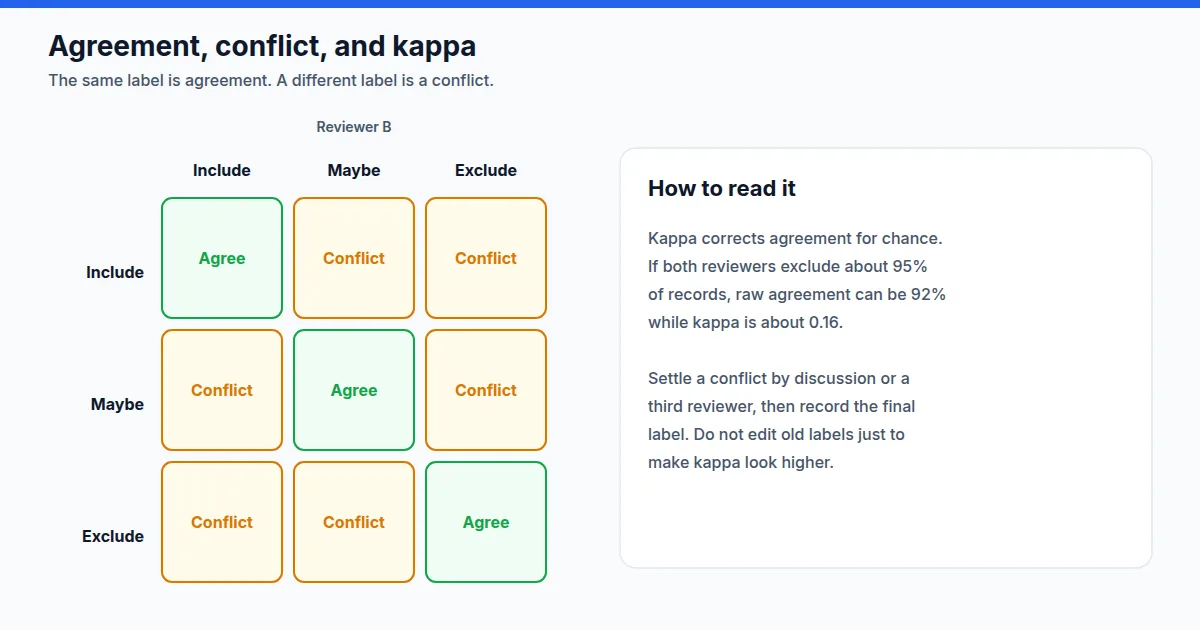
- Conflict: the two screeners choose different labels (Include vs Exclude, Include vs Maybe, or Maybe vs Exclude).
- Same: both choose the same label (Include/Include, Maybe/Maybe, or Exclude/Exclude).
- A Maybe is a disagreement that needs a resolution. It is a full label of its own, with the same path as any other off-diagonal pair.
The conflict matrix
Think of a 3×3 grid with Screener A down the left (Include / Maybe / Exclude) and Screener B across the top. The diagonal cells are agreements. Everything off the diagonal is a conflict to resolve. The queue is the set of non-diagonal cells.
Cohen's kappa during title and abstract screening
Cohen's kappa is chance-corrected agreement. It asks how much the observed agreement exceeds the agreement expected from each screener's base rates. Kappa can look low when raw agreement looks high, if most records are Exclude. That pattern is ordinary at title and abstract. Read kappa across the batch, beside the queue. A single record is settled by the resolution, which the worked example below does not touch.
This example is synthetic. It collapses Maybe into a binary so the arithmetic is easy to check. Each screener Includes 5% and Excludes 95%. Observed raw agreement is 92%. Expected agreement from the marginals is 0.05×0.05 + 0.95×0.95 = 0.0025 + 0.9025 = 0.905. Kappa is (0.92 − 0.905) / (1 − 0.905) = 0.015 / 0.095 = 0.158, about 0.16.
McHugh (Biochemia Medica, 2012;22:276-282) prints two ways to name that number. Cohen's bands, as McHugh quotes them, run from no agreement at 0 or below, through 0.01–0.20 none to slight, 0.21–0.40 fair, 0.41–0.60 moderate, 0.61–0.80 substantial, and 0.81–1.00 almost perfect. McHugh's own table is stricter: 0–0.20 none, 0.21–0.39 minimal, 0.40–0.59 weak, 0.60–0.79 moderate, 0.80–0.90 strong, and above 0.90 almost perfect. A kappa of 0.16 sits in the lowest band on both lists. McHugh argues that Cohen's labels are too lenient for health research, because they can treat a kappa as low as 0.41 as acceptable. With an imbalanced 3×3, report kappa with the marginals. The band name is a rough label for the batch.
Most of that 90.5% expected agreement is both people excluding. Shared Excludes raise the chance correction and pull kappa down. Balanced include rates can raise kappa when raw agreement barely moves. That is the formula on this synthetic table, which is why kappa sits next to the matrix.
A recoded binary scheme belongs in the protocol before screening starts. Relabeling afterwards, or treating Maybe as an automatic Include, changes the statistic you said you would report.
Resolution queue: how the work moves
- Put all disagreements and all Maybes into a single queue.
- Resolution path: discuss, and if the disagreement is about interpretation, ask another person to arbitrate, then record the resolved label. Section 4.6.4 describes discussion first and arbitration when the cause is interpretation.
- The adjudicator sees both initial labels, and short rationales if you captured them.
- A Maybe follows the same resolution path as any other disagreement.
- Leave the original labels in place when you compute kappa. A recode belongs in the protocol, written up front.
Protocol decisions to make before you start
- Dual or single screening at title and abstract. Section 4.6.4 accepts one person for that pass and asks you to define disagreement handling in advance.
- Which labels you will use, and how Maybe enters the queue.
- Who resolves conflicts, and when a third person is asked to arbitrate.
- How kappa will be reported: the scope, the unit, and any recoding rule.
Doing it in Study Screener
These steps were checked against the application source on 8 November 2026. The labels below are the strings in that source.
The owner invites from the workspace team strip. The control and the dialog are both labeled "Invite team members". The role selector offers "Reviewer (can screen)" and "Viewer (read-only)". Pending invitations have Resend and Cancel. The dialog does not offer an arbiter role.
Reviewers record Include, Maybe, or Exclude while the project is blinded. In that state the team strip reads "Blinded" and hides the member count and kappa. Hovering or focusing that pill shows: "Team results are blinded. Conflicts and maybes appear here once the project is opened."
A saved screening decision calls check_and_unblind_project, which opens the project when every owner and reviewer membership has a decision on every study. Viewers are outside that count. An owner-only unblind route also exists. The button that calls it is labeled "Reveal Team Results" and sits on My Library's shared-libraries tab while results are blinded. That button is not on the owner's own library tab in this source.
Once the project is open, the team strip shows the member count, the word "Open", and kappa for reviewer pairs (up to two values, each to two decimal places). Pending disagreements are a top-bar pill labeled like "Conflicts 1 · Maybes 1". Opening the pill shows the queue. Search appears when the list has more than four rows. Export CSV is inside the pill. Choosing a title focuses that study.
Include and Exclude on selected rows are available to the project owner and to a member whose role is arbiter. The resolve action is refused while the project is still blinded. It writes a resolution row with the final decision, who resolved it, when, and optional notes, and it leaves the original votes in place. The inbox then reloads from the server. When the pending count is zero and something has been resolved, the pill shows a green check and the label "Resolved". Clearing the queue shows a one-time notice, "All disagreements are resolved" and "Downloads are in the left column." Opening an already resolved project keeps the check and does not repeat that notice. Export CSV stays inside the pill. A reviewer who cannot resolve still sees the list, without those buttons, and a line that original votes are kept and the project owner records the final decision.
What to report
PRISMA 2020 (Page and colleagues, BMJ 2021;372:n71, published 29 March 2021) is the reporting guideline for the review. Its methods item on study selection asks you to report how many reviewers screened each record and each report, whether they worked independently, and, where you used them, automation tools. The statement also provides a flow diagram for the counts from identification through inclusion. Describe the screening in language aligned with PRISMA 2020. The Handbook section above is the conduct guidance: document selection in enough detail to complete a flow diagram, and keep the resolved label as the decision that flows forward.
Where this sits in the review
Screening sits between the search export and full text. The screening overview is What is screening in a systematic literature review. The manual project path is the beginner's step-by-step guide and Getting started with systematic reviews. Automated screening is compared separately in AI-assisted vs manual systematic review screening. After inclusion, cell-by-cell extraction disagreements are the next stage: resolving dual-extraction disagreements.
Read Cohen's kappa beside the queue. In the synthetic example, 92% raw agreement and a kappa of about 0.16 happen together because almost every record is an Exclude. That is a prompt to look at where the off-diagonal cells sit, Include against Exclude and anything with a Maybe. Keep the queue moving, record the resolution, and let the statistic follow the method you wrote down.